

Model Quantization and Compilation
The conversion of the floating-point model to the Horizon board-side deployable model will be completed in the Convert Model phase, after which you will get a model that can run on the Horizon computing platform. Before performing the conversion, make sure you have successfully passed the model check as described in the Check the Model section.
During the conversion, some important procedures such as model optimization and calibration quantization must prepare the data in line with model pre-processing requirements. You can refer to Data Preparation - Model Calibration Set Preparation section to prepare the calibration data in advance.
Convert the Model Using the hb_compile Tool
The model conversion process is performed using the hb_compile tool, please refer to section Model Quantized Compilation for the usage of the tool and the related specific configuration and parameters.
Model Conversion Interpretation
Model conversion is completed from a floating-point model to a board-side deployable model supported by Horizon's computing platform. To make this model run quickly and efficiently on the embedded end, model conversion focuses mainly on two phases: input data processing and model optimization compilation, and this section will focus on these two problems in turn.
In terms of Input data processing, Horizon's edge computing platform can provide hardware-level solutions for specific types of input channels, but the output of these solutions may not comply with the input requirements of your models.
For example, the video processing sub-systems for video channels have the abilities to crop and scale images or optimize the image quality. The output of these sub-systems are mostly in the YUV420 format, however, the algorithm models are often trained based on commonly-used image formats such as bgr/rgb.
To solve this problem, Horizon provides 2 kinds of input descriptions for each converted model: The one is used for the original floating-point model input (input_type_train and input_layout_train); while the other one is used for the input data ( input_type_rt ) of the edge platform that you are going to use.
For the frequently-used image data pre-processing, such as mean and scale, the edge platform data formats such as yuv420 are no longer suitable for such operations, therefore, we integrate these common image pre-processing into the model. After the above two processes, the input part of the converted model will be shown as follows
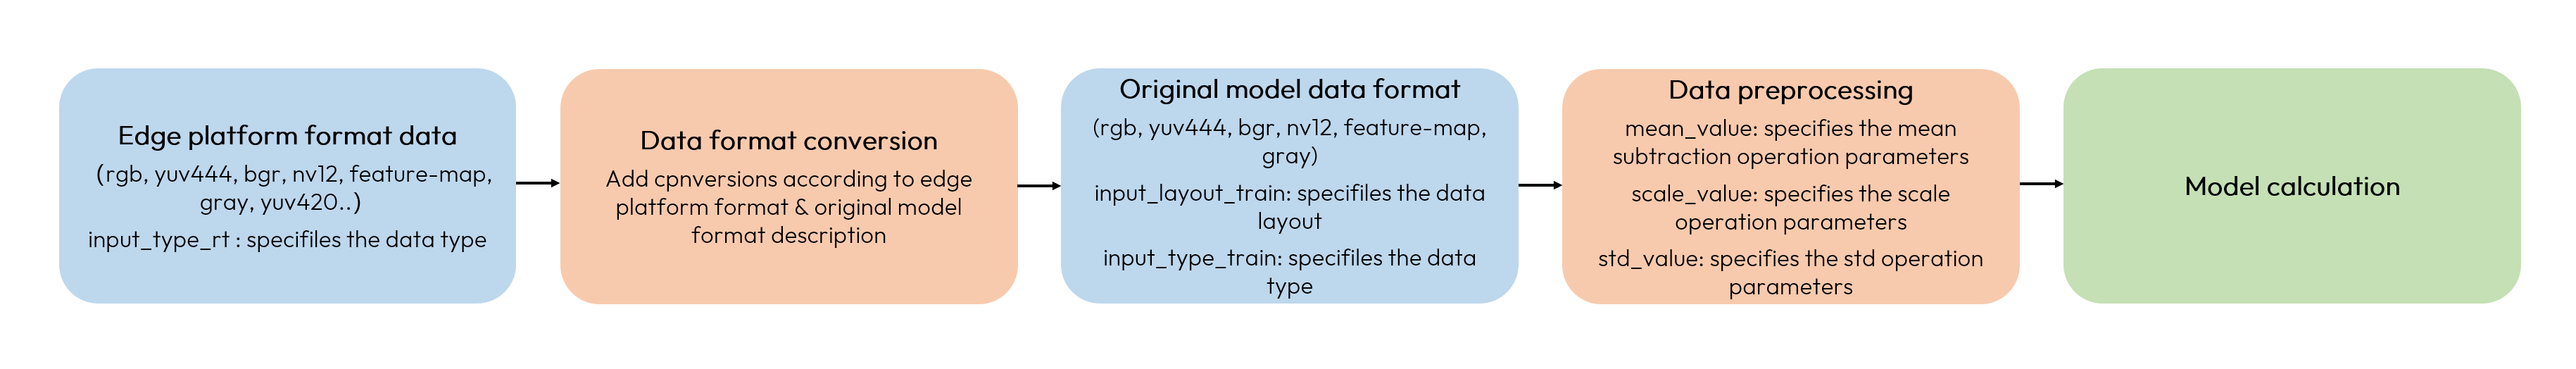
There are only 2 types of data layouts in the above diagram: NCHW and NHWC.
Wherein, N denotes quantity, C denotes channel, H denotes height and W denotes width.
The two different layouts reflect different memory access characteristics.
The NHWC layout are more often used by the TensorFlow models; while the NCHW layout is used by the Caffe models.
Although Horizon's edge platform doesn't restrict the data layout, there is still a requirement: the input_layout_train must be consistent with the data layout of the original floating-point model, as specifying correct data layout is the basis for smooth data parsing.
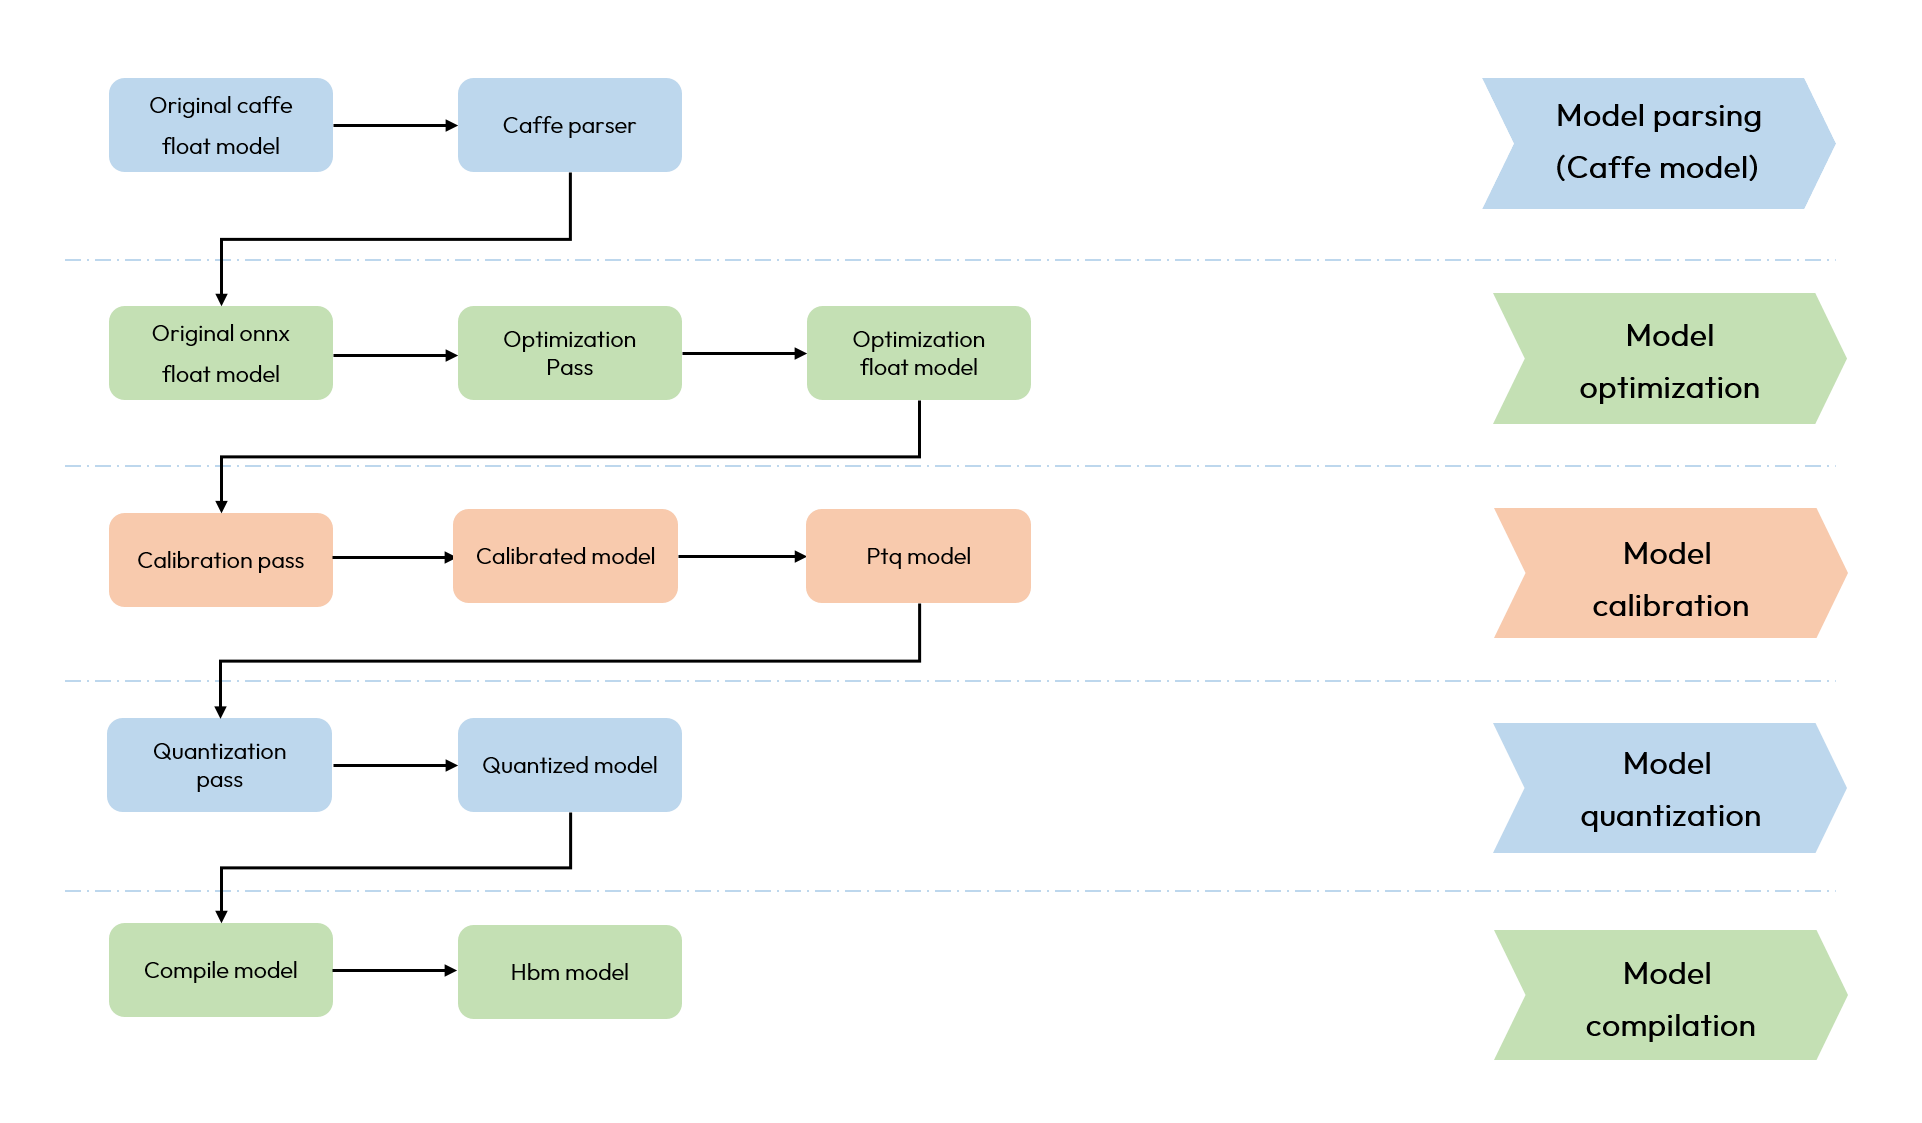
Model Optimization and Compilation: It includes several important steps, including model parsing, model optimization, model calibration and quantification, and model compilation, and its internal working process is shown in the figure below.
-
Model Parse Stage: It completes the conversion from Caffe floating-point model to ONNX floating-point model. This stage will name the operator (with a unique name) for the unnamed node/tensor, producing an
original_float_model.onnx, and the computing accuracy of this ONNX model is float32. -
Model Optimization Stage: It implements some operator optimization strategies for the model that are applicable to the Horizon platform, such as BN fusion to Conv, etc. The output of this phase is an
optimized_float_model.onnx. The computational accuracy of this ONNX model is still float32, which will not affect the computational results of the model after optimization. -
Model Calibration Stage: It uses the calibration data you provide to calculate the necessary quantization parameters, and the quantization parameters corresponding to each node calculated from the calibration data will be saved in the calibration node. The output of this phase is a
calibrated_model.onnx. After model calibration, some processing will be performed on the model as well, the output of this process is aptq_model.onnx. -
Model Quantization Stage: It uses Horizon's model compiler, which uses the generated model during the model calibration stage(ptq_model.onnx), to perform model quantization according to your pre-processing configuration (including the color conversion between input_type_rt to input_type_train, the handling of mean/scale, etc). The output of this phase is a
quantized_model.bc. The loss of accuracy due to model quantization can be evaluated using this model. If during model quantization there exists a situation of removing nodes at the input/output, aquantized_removed_model.bcwill also be saved. In this scenario, we recommend you to use this HBIR model to compare with the final generated hbm model if you need to do consistency comparison later.
Please note that if input_type_rt is nv12, the input layout of quantized.bc is NHWC.
- Model Compilation Stage: It uses Horizon's model compiler to convert the quantized model computational instructions and data supported by the Horizon platform. The output of this stage is a *.hbm model, this hbm model is the model that will be subsequently run on the Horizon Edge embedded platform, which is the final output result of the model conversion.
Interpret Conversion Results
This section will introduce the interpretation of successful model conversion status and the analysis of unsuccessful conversions in turn.
To confirm the success of the model conversion, you need to check the similarity information of nodes and output tensors, the compile status information and the working_dir output.
Similarity Information
The similarity information will be printed in the console output after compile,
after successful conversion, it will also be saved to the log file named hb_compile.log under the path where the compile command is executed,
which takes the following form:
As shown above:
-
The Node and NodeType represents node name and type.
-
The ON represents the node executed device.
-
The TensorName represents output tensors name.
-
The Threshold represents to the calibration threshold at each layer, which is used to provide feedback to Horizon technical support in abnormal states and is not of concern in normal conditions.
-
The Calibrated Cosine represents the cosine similarity result between the corresponding Node/Output Tensor of the
optimized_float_model.onnxand thecalibrated_model.onnx. -
The Quantized Cosine represents the cosine similarity result between the corresponding Node/Output Tensor of the
optimized_float_model.onnxand thequantized_model.bcgenerated after model quantization. -
The Output Data type represents the node output data type, range with ['si8', 'si16', 'si32', 'si64', 'ui8', 'ui16', 'ui32', 'ui64', 'f32'].
The cosine similarity is only a reference for the stability of the quantized data and does not have an obvious direct correlation with model accuracy. Refer to the following table for interpretation:
Compile Status Information
For the compile status information, after a successful conversion, the model's dependencies and parameters will be output on the console, as follows:
-
model deps info: Versions of tools dependent during model compilation.
-
model_parameters info: Information of
model parametersspecified in the model compilation configuration file. -
input_parameters info: Information of
input parametersspecified in the model compilation configuration file. -
calibration_parameters info: Information of
calibration parametersspecified in the model compilation configuration file. -
compiler_parameters info: Information of
compiler parametersspecified in the model compilation configuration file. -
memory info: Information related to memory usage during various stages of model compilation.
Conversion Output
The conversion output is stored in the path specified by the conversion configuration parameter working_dir. After successful model conversion, you can get the following files in this directory (* part is what you specify by the conversion configuration parameter output_model_file_prefix):
-
*_original_float_model.onnx
-
*_optimized_float_model.onnx
-
*_calibrated_model.onnx
-
*_ptq_model.onnx
-
*_quantized_model.bc
-
*_quantized_removed_model.bc (when there is a situation of removing nodes at the input/output)
-
*.hbm
-
*_advice.json
-
*_quant_info.json
-
*_node_info.csv
-
*.html
-
*.json
-
hb_compile.log
The purpose and usage suggestions for each output are listed in the table below:
| Output | Generation stage | Compute precision / quantization state | Purpose and usage suggestions | Used in consistency comparison | Provide to Horizon when debugging |
|---|---|---|---|---|---|
*_original_float_model.onnx | Model parsing | float32, identical to the original floating-point model | Used to check whether the original floating-point model is parsed correctly by the tool. In general you do not need this model. When conversion results are abnormal, providing this model to Horizon technical support will help resolve the issue quickly. | Used as the baseline input for optimized_float ↔ original_float consistency comparison | Yes |
*_optimized_float_model.onnx | Model optimization | float32, still equivalent to the floating-point model after operator fusion and other equivalent optimizations | Used to check whether the optimization stage introduces deviations and whether operator fusion and replacement results meet expectations. By visually comparing with the original_float model, you can clearly see some operator-structure-level changes, but none of them affects the computational accuracy. In general you do not need this model. Providing it to technical support helps resolve issues quickly when abnormalities occur. | Compared with original_float and calibrated_model respectively | Yes |
*_calibrated_model.onnx | Model calibration | Fake-quantized, simulating quantization behavior in the floating-point domain | Used to check whether calibration thresholds are reasonable and whether the calibration stage introduces large errors. This model is an intermediate product obtained by the model conversion toolchain by taking the floating-point model after structural optimization, calculating the quantization parameters corresponding to each node from the calibration data and saving them in the calibration node. | Compared with optimized_float and ptq_model respectively | Yes |
*_ptq_model.onnx | Model calibration - pre-quantization | Lookup-table operators are fixed-point; other operators are still fake-quantized | Used to check whether lookup-table operator fixed-pointization introduces errors. This model is the product of pre-quantization performed by the model conversion toolchain on the calibrated model. | Compared with calibrated_model and quantized_model.bc respectively | Yes |
*_quantized_model.bc | Model quantization | Fully fixed-point HBIR model | Calibration and quantization are complete; the quantized accuracy loss can be examined here. This is a mandatory model in the accuracy verification process and is theoretically consistent with hbm in accuracy. For usage refer to Model Accuracy Evaluation section. | Compared with ptq_model and hbm respectively | Yes |
*_quantized_removed_model.bc | Model quantization - when there is a situation of removing nodes at the input/output | Fully fixed-point HBIR model with removable input/output-side nodes removed | When there is a situation of removing nodes at the input/output during model quantization, the removed-node HBIR model will be saved automatically. In this scenario, if you need to perform consistency comparison later, we recommend using this model against the final hbm model. | Yes (only when there is a node-removal scenario) | Yes (if generated) |
*.hbm | Model compilation | Instruction file that can be loaded and executed on the board | The model that can be loaded and executed on the Horizon computing platform, theoretically consistent with quantized.bc in accuracy. Combined with Embedded Application Development section you can deploy and run the model quickly. To ensure that model performance and accuracy meet expectations, we strongly recommend completing the analyses in Model Performance Evaluation and Model Accuracy Evaluation sections before moving on to application development and deployment. | Overall output compared with quantized.bc (or quantized_removed_model.bc) | Yes |
*_advice.json | Model compilation | Advisory information printed by op checker | Stores the results printed by the Horizon model compiler op checker during compilation, including compiler-level optimization suggestions for model structure and CPU operator hints. | No | No (may be provided as auxiliary information in case of abnormality) |
*_quant_info.json | Model calibration / quantization | Calibration and quantization information (thresholds, scale, etc.) for operators | The file records the calibration and quantization information of operators, which can be used to check whether the quantization configuration has been applied as expected and whether thresholds are abnormal. | No | No (may be provided as auxiliary information in case of abnormality) |
*_node_info.csv | Model quantized compilation | Operator deployment information and similarity results | The file records the cosine similarity and other information of operators after successful conversion, identical to the similarity information printed by hb_compile in the console. It can be used to view the CPU / BPU distribution of operators and the similarity of each operator. | No | Yes (provide when abnormal) |
*.json / *.html | Model compilation | Model static performance evaluation file | The static performance evaluation file of the model, used to review the static performance estimation of the BPU portion. .html is more readable; .json is easier to process programmatically. | No | No |
hb_compile.log | Across the entire compilation process | Compilation log | The log file generated by compilation. It records the reasons for conversion success or failure, similarity information, and operator deployment information. | No | Yes (must be provided when abnormal) |
Before running on the board, we strongly recommend you to proceed the procedures as described in the Model Performance Evaluation and Model Accuracy Evaluation sections, to avoid extending the model conversion problem to the subsequent embedded terminal.
If any of the above-mentioned 3 outputs of verifying the success of the model conversion is missing, there must be something wrong with the conversion. In such cases, the compile tool will output error messages to your console in case of errors. For example, if we do not configure the prototxt and caffe_model parameters during the Caffe model conversion, the tool gives the following message:
If the above steps do not help you find the problem, please feel free to raise your question in Horizon Developer Community, and we will provide support.
What to Check After the Compiled Output
After getting the compiled outputs, we recommend continuing the verification along the following three branches:
-
Performance branch: Refer to Model Performance Evaluation section. First use the
.html/.jsonstatic evaluation files to confirm the BPU-side performance upper bound, then measure on-board via thehrt_model_exectool. If the results do not meet expectations, refer to Performance Tuning Guide section. -
Accuracy branch: Refer to Model Accuracy Evaluation section. Use
quantized_model.bcto run dataset-level accuracy evaluation on the development machine (hbmandquantized.bcare theoretically consistent in accuracy). If accuracy does not meet expectations, refer to ONNX Model Accuracy Tuning Guide section. -
Consistency branch: Refer to ONNX Model Deployment Consistency Analysis section. Perform stage-by-stage consistency verification across
original → optimized → calibrated → ptq → quantized.bc → hbm. When structural changes (Pyramid / Resizer / multi-batch / nv12 input, etc.) affect the analysis, follow the section for handling.